

Resources
Resources
GPU Servers in Malaysia
Fuel your AI projects with IP ServerOne’s bare metal GPU servers—dedicated, affordable, and purpose–built for AI/ML, HPC, and other compute-intensive workloads.
Powered by NVIDIA GPU technology, our bare metal GPU servers are engineered for AI, machine learning (ML), deep learning, and high-performance computing workloads. Designed for model training, fine-tuning, inference, and large-scale data processing, they deliver consistent, high-throughput performance with full hardware access in a dedicated single-tenant environment. Our GPU lineup includes RTX 3090, RTX 4090, RTX 5090, RTX PRO 6000 Blackwell, RTX 6000 Ada, and enterprise-grade accelerators such as the H200 NVL — enabling secure, scalable infrastructure for data-intensive AI applications. With no virtualization overhead, enhanced data control, and 24/7 local technical support, our GPU servers provide reliable, high-performance infrastructure for production-grade AI deployments.
The Challenges of AI: High Costs, Complex Infrastructure, and Data Risks
High Cost of GPUs
Training complex models, running deep learning, natural language processing (NLP), or scientific simulations all require GPUs—an expensive upfront investment that creates a major barrier.
Infrastructure Design and Maintenance
AI/ML workloads require specialized networking, storage, and compute resources, which can be challenging to configure optimally. Hardware failures and GPU degradation can disrupt operations.
Security & Data Sovereignty
Running AI models on shared cloud GPUs exposes sensitive data to potential breaches. Industries like healthcare, finance, and government must ensure compliance and mitigate these risks.
NovaGPU: On-Demand GPUs for Your AI Projects
Run training, fine-tuning, and inference with pay-as-you-go GPU compute. Get started with the RTX 5090 at MYR 3.05/hour, or choose RTX PRO 6000 Blackwell at MYR 9.54/hour and H200 NVL from MYR 19.09/hour.
Start today and scale effortlessly whenever you need.
Benefits of GPU Servers
Accelerate AI Deployment
Speed up AI and machine learning projects with GPUs from RTX 3090, RTX 4090, RTX 5090, RTX 6000 Ada, RTX PRO 6000 Blackwell, to H200 NVL — delivering faster training, fine-tuning, and real-time inference for demanding AI applications.
Cost-Effective AI Solutions
Get premium GPU servers at competitive rates with flexible subscription models, ensuring predictable pricing and no hidden fees—without compromising quality or reliability.
Secure & Dedicated Infrastructure
Run AI workloads on bare metal GPU servers with dedicated resources, ensuring full control, uncompromised performance, and strict data sovereignty in a single-tenant environment.
Peace of Mind
Enjoy 24/7 support and hosting in a secure, high-availability Tier III data center, so you can focus on your core business while we handle your infrastructure.
Versatile Use Cases
Host AI applications with dedicated GPU power, delivering the performance needed for LLMs, generative AI, scientific simulations, and other compute-intensive workloads.
Simplified Deployment and Management
Let us handle the hardware setup, configuration, and ongoing maintenance, so you can focus on bringing your innovations to life.
Dream Big, Compute Bigger!
Unleash the full potential of your projects with high-performance GPU servers today.
Key Features of GPU Servers
Dream Big, Compute Bigger!
Unlock the full potential of your AI projects with powerful GPU servers at a fraction of the cost.
High-Performance NVIDIA GPUs
Leverage GPUs including the RTX 3090, RTX 4090, RTX 5090, RTX 6000 Ada, RTX PRO 6000 Blackwell, and H200 NVL for fast AI/ML training, fine-tuning, inference, and demanding workloads like simulations, rendering, and high-end graphics.
Custom GPU Servers for Any AI Workload
Customize your server with the GPU, AI models, memory, and storage you need for maximum performance—perfect for chatbots, AI agents, automation, and more—while ensuring full compliance and security.
Optimized for AI/ML & HPC Workloads
Designed for demanding AI/ML and high-performance computing (HPC) tasks, our GPU servers ensure high-speed training, precise inference, and reliable performance for complex models and custom applications.
Model Fine-Tuning
Fine-tune your pre-trained models with ease using our GPU servers, ensuring the accuracy and performance needed for your unique applications in a controlled, isolated environment.
24/7 Support Assistance
Benefit from around-the-clock support from our experienced engineers, ensuring your GPU servers run smoothly, with quick issue resolution to maintain optimal performance.
Enterprise-Grade Hosting
Rest easy knowing your applications are hosted in our Tier III data center, providing top-tier security, reliability, and high availability for mission-critical workloads.
GPUs Benchmark
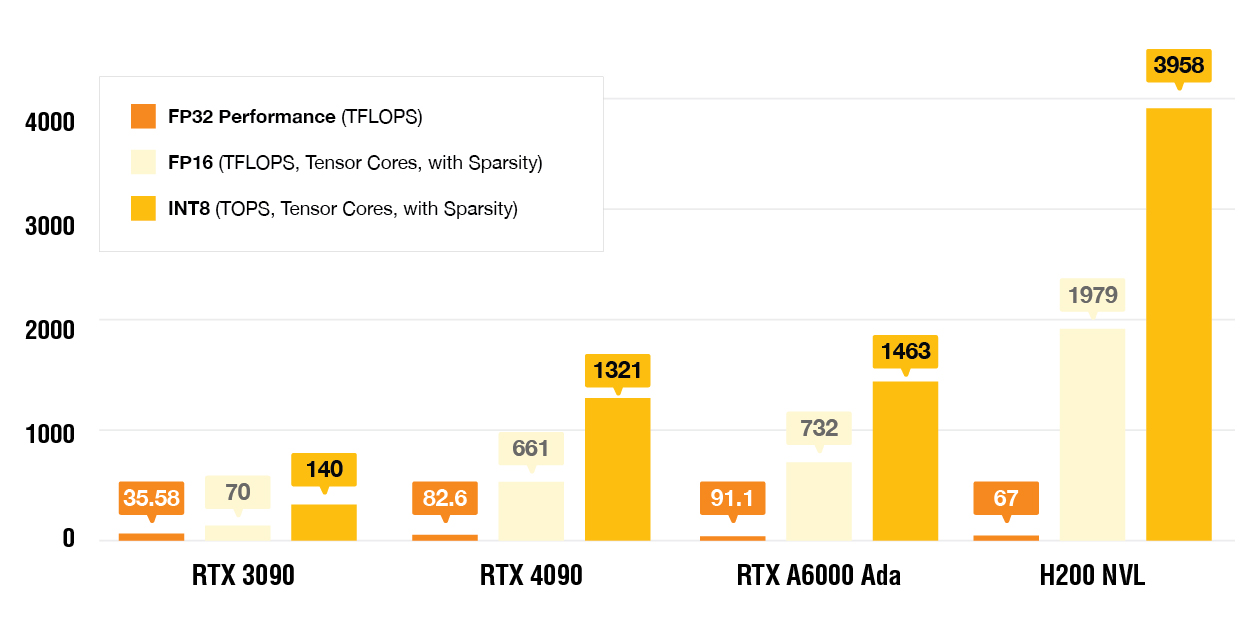
GPU Compute Performance
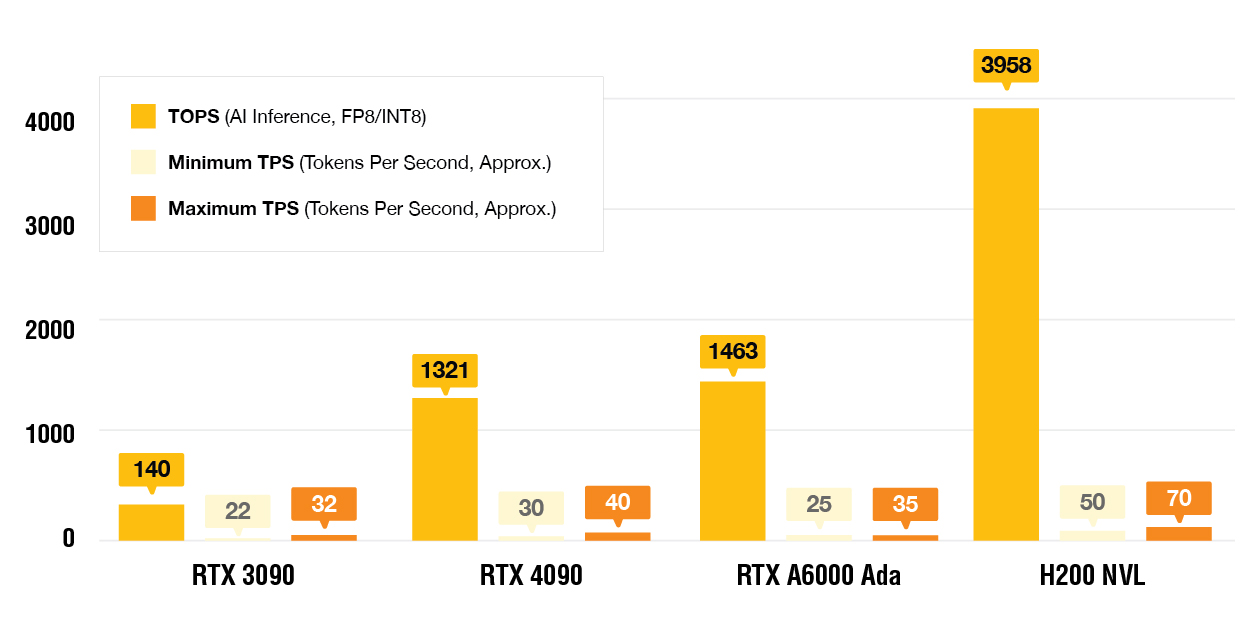
AI Processing Power: TOPS vs TPS
Notes:
- TOPS (Tera Operations Per Second) measures peak AI inference performance with Tensor Cores, but real-world results depend on workload and software optimization.
- TPS (Tokens Per Second) varies by model (e.g., LLaMA, GPT), batch size, and optimizations, making figures approximate based on benchmarks. For detailed benchmarks, visit NVIDIA’s official website.
Available GPU Options
Choose from dedicated NVIDIA GPUs for AI development, LLMs, RAG, generative AI, visualization, and high-performance computing (HPC). Explore each GPU to find the right fit for your workload.
NVIDIA GeForce RTX 3090
NVIDIA GeForce RTX 4090
NVIDIA GeForce RTX 5090
NVIDIA RTX 6000 Ada
NVIDIA RTX PRO 6000 Blackwell
NVIDIA H200 NVL Tensor Core
NVIDIA GeForce RTX 3090
The NVIDIA RTX 3090 features 24GB GDDR6X memory and NVIDIA Ampere architecture, providing dedicated, non-shared GPU compute for AI development, experimentation, and GPU-accelerated applications.
Ideal For
- AI and machine learning development
- RAG applications
- AI chatbots and assistants
- Image generation
- Model experimentation and inference
NVIDIA GeForce RTX 4090
The NVIDIA RTX 4090 features 24GB GDDR6X memory and NVIDIA Ada Lovelace architecture, delivering dedicated, non-shared GPU compute for demanding AI development and generative AI workloads.
Ideal For
- Generative AI applications
- RAG and knowledge assistants
- AI agents
- Image and video generation
- Model fine-tuning and inference
NVIDIA GeForce RTX 5090
Built on NVIDIA’s Blackwell architecture, the RTX 5090 features 32GB GDDR7 memory, 21,760 CUDA cores, and 5th-generation Tensor Cores, providing dedicated GPU compute for demanding AI and compute workloads.
Ideal For
- Larger generative AI applications
- AI agents and RAG
- Model fine-tuning
- LLM inference
- AI development and experimentation
NVIDIA RTX 6000 Ada
The NVIDIA RTX 6000 Ada Generation features 48GB GDDR6 memory and NVIDIA Ada Lovelace architecture, combining professional GPU capabilities with dedicated, non-shared compute for AI, visualization, rendering, and other demanding workloads.
Ideal For
- AI development and inference
- Computer vision
- 3D visualization
- Rendering and content creation
- Engineering and simulation workloads
*Note: This option is available only on Bare Metal GPU.
NVIDIA RTX PRO 6000 Blackwell
Built on NVIDIA’s Blackwell architecture, the RTX PRO 6000 Blackwell features 96GB GDDR7 memory and professional GPU capabilities, providing substantial memory capacity for larger AI models, memory-intensive workloads, and professional visualization.
Ideal For
- Larger AI models
- AI agents and RAG
- LLM inference
- Computer vision
- 3D visualization and rendering
- Professional AI and compute workloads
NVIDIA H200 NVL Tensor Core
The NVIDIA H200 NVL features 141GB HBM3e memory and NVIDIA Hopper architecture, delivering high-bandwidth GPU memory for large-scale AI, LLM, and high-performance computing (HPC) workloads.
Ideal For
- Large language models (LLMs)
- LLM training and inference
- AI agents and RAG at scale
- Generative AI workloads
- High-performance computing (HPC)
- Large-scale AI applications
Note: Performance varies by workload, model, software, and configuration. See NVIDIA’s official specifications and benchmarks for detailed information.
Find the Right GPU for Your AI Needs
Comparing RTX 3090, RTX 4090, RTX 5090, RTX 6000 Ada, RTX PRO 6000 Blackwell, and H200 NVL
View GPU Comparisons
| Specification | RTX 3090 | RTX 4090 | RTX 5090 | RTX 6000 Ada | RTX PRO 6000 Blackwell | H200 NVL |
|---|---|---|---|---|---|---|
| Service Offering | Bare-metal + NovaGPU | Bare-metal + NovaGPU | Bare-metal + NovaGPU | Bare-metal | NovaGPU | Bare-metal + NovaGPU |
| Architecture | Ampere | Ada Lovelace | Blackwell | Ada Lovelace | Blackwell | Hopper |
| CUDA Cores | 10,496 | 16,384 | 21,760 | 18,176 | 24,064 | 16,896 |
| Tensor Cores | 328 (3rd Gen) | 512 (4th Gen) | 680 (5th Gen) | 568 (4th Gen) | 752 (5th Gen) | 528 (4th Gen) |
| AI TOPS / Tensor Performance | 285 AI TOPS | 1,321 AI TOPS | 3,352 AI TOPS | 1,457 AI TOPS | 4,000 AI TOPS | 3,341 TFLOPS |
| GPU Memory (VRAM) | 24GB GDDR6X | 24GB / 48GB | 32GB GDDR7 | 48GB GDDR6 | 96GB GDDR7 | 141GB HBM3e |
| Memory Bandwidth | 936 GB/s | 1,008 GB/s | 1,792 GB/s | 960 GB/s | 1,597 GB/s | 4.8 TB/s |
| AI Use Case | AI development, experimentation, inference, RAG and generative AI | Generative AI, RAG, model fine-tuning and inference | Generative AI, AI agents, model fine-tuning and LLM inference | AI development and inference, computer vision and professional visualization | Larger AI models, AI agents, LLM inference, RAG, scientific computing and professional AI workloads | Large language models, generative AI, RAG, AI inference and HPC |
IMPORTANT NOTES
- Source of Data: Based on NVIDIA’s official specifications, community benchmarks, and calculated estimates; some figures are approximations due to limited public disclosure.
- Sparsity Performance: Results reflect peak values under ideal conditions. Actual results may vary based on workload and how well the data fits the hardware’s sparsity requirements.
- Purpose: Helps users compare GPUs for AI/ML workloads by analyzing key specifications such as Tensor Core performance, VRAM, and memory bandwidth. Not a definitive recommendation.
- Accuracy: Data is accurate as of December 2, 2025, but performance may vary based on software, workloads, and hardware configurations. Users should verify details for their needs.
- Further Information: For the latest specifications, check NVIDIA’s website or community forums. We are not responsible for external sources' accuracy.
GPU Plans and Pricing
SINGLE GPU Plans
Single GPU plans include:
- RAID: Non-RAID
- Bandwidth: 500Mbit/s
- Power Supply: Single
| Single GPU Server | ||||||||
| GPU Model | GPU Cards | VRAM | Per GPU Performance | CPU | Processor | RAM | Hard Drive | Price / Month |
| RTX 3090 | 1 x NVIDIA GeForce RTX 3090 | 24GB | FP32 TFLOPS: 35.6 AI TOPS: 285 GPU Memory Bandwidth: 936.2GB/s | 16 Cores 3.0GHz | AMD EPYC™ 7313 | 64GB | 1 x 3.8TB NVME/SSD | MYR 1,599+ |
| RTX 4090 | 1 x NVIDIA GeForce RTX 4090 | 24GB | FP32 TFLOPS: 82.6 AI TOPS: 1,321 GPU Memory Bandwidth: 1,008GB/s | 16 Cores 3.0GHz | AMD EPYC™ 7313 | 64GB | 1 x 3.8TB NVME/SSD | MYR 2,199+ |
| RTX 5090 | 1 x NVIDIA GeForce RTX 5090 | 32GB | FP32 TFLOPS: 104.8 AI TOPS: 3,352 GPU Memory Bandwidth: 1,792GB/s | 16 Cores 3.0GHz | AMD EPYC™ 7313 | 64GB | 1 x 3.8TB NVME/SSD | Get Quote |
| RTX 6000 Ada | 1 x NVIDIA RTX 6000 Ada | 48GB | FP32 TFLOPS:91.1 AI TOPS:1,457 GPU Memory Bandwidth:960GB/s | 16 Cores 3.0GHz | AMD EPYC™ 7313 | 64GB | 1 x 3.8TB NVME/SSD | MYR 6,450+ |
| RTX 6000 Ada | 1 x NVIDIA RTX 6000 Ada | 48GB | FP32 TFLOPS:91.1 AI TOPS:1,457 GPU Memory Bandwidth:960GB/s | 16 Cores 3.0GHz | AMD EPYC™ 7313 | 256GB | 1 x 3.8TB NVME/SSD | MYR 6,850+ |
| RTX PRO 6000 Blackwell | 1 x NVIDIA RTX PRO 6000 Blackwell | 96GB | FP32 TFLOPS:120 AI TOPS:4,000 GPU Memory Bandwidth:1,597GB/s | 16 Cores 3.0GHz | AMD EPYC™ 7313 | 128GB | 1 x 3.8TB NVME/SSD | MYR 8,850+ |
| RTX PRO 6000 Blackwell | 1 x NVIDIA RTX PRO 6000 Blackwell | 96GB | FP32 TFLOPS:120 AI TOPS:4,000 GPU Memory Bandwidth:1,597GB/s | 16 Cores 3.0GHz | AMD EPYC™ 7313 | 256GB | 1 x 3.8TB NVME/SSD | MYR 9,850+ |
| H200 NVL | 1 x NVIDIA H200 NVL | 141GB | FP32 TFLOPS: 60 AI TOPS: 3,341 GPU Memory Bandwidth: 4,800GB/s | 16 Cores 3.0GHz | AMD EPYC™ 7313 | 64GB | 1 x 3.8TB NVME/SSD | Get Quote |
DUAL GPU Plans
DUAL GPU plans include:
- RAID: non-RAID
- Bandwidth: 500Mbit/s
- Power Supply: Dual
| Dual GPU Server | ||||||||
| GPU Model | GPU Cards | VRAM | Per GPU Performance | CPU | Processor | RAM | Hard Drive | Price / Month |
| RTX 4090 | 2 x NVIDIA GeForce RTX 4090 | 48GB (2 x 24GB) | FP32 TFLOPS: 82.6 AI TOPS: 1,321 GPU Memory Bandwidth: 1,008GB/s | 16 Cores 3.0GHz | AMD EPYC™ 7313 | 256GB | 2 x 7.6TB NVME/SSD | MYR 6,099+ |
| RTX 5090 | 2 x NVIDIA GeForce RTX 5090 | 64GB (2 x 32GB) | FP32 TFLOPS: 104.8 AI TOPS: 3,352 GPU Memory Bandwidth: 1,792GB/s | 16 Cores 3.0GHz | AMD EPYC™ 7313 | 128GB | 2 x 7.6TB NVME/SSD | Get Quote |
| RTX 6000 Ada | 2 x NVIDIA RTX 6000 Ada | 96GB (2 x 48GB) | FP32 TFLOPS: 91.1 AI TOPS: 1,457 GPU Memory Bandwidth: 960GB/s | 16 Cores 3.0GHz | AMD EPYC™ 7313 | 256GB | 2 x 7.6TB NVME/SSD | MYR 9,450+ |
| RTX PRO 6000 Blackwell | 2 x NVIDIA RTX PRO 6000 Blackwell | 192GB (2 x 96GB) | FP32 TFLOPS:120 AI TOPS:4,000 GPU Memory Bandwidth:1,597GB/s | 16 Cores 3.0GHz | AMD EPYC™ 7313 | 256GB | 2 x 7.6TB NVME/SSD | MYR 14,250+ |
| H200 NVL | 2 x NVIDIA H200 NVL | 282GB (2 x 141GB) | FP32 TFLOPS: 60 AI TOPS: 3,341 GPU Memory Bandwidth: 4,800GB/s | 16 Cores 3.0GHz | AMD EPYC™ 7313 | 128GB | 2 x 7.6TB NVME/SSD | Get Quote |
QUAD GPU Plans
QUAD GPU plans include:
- RAID: non-RAID
- Bandwidth: 500Mbit/s
- Power Supply: Dual
| Quad GPU Server | ||||||||
| GPU Model | GPU Cards | VRAM | Per GPU Performance | CPU | Processor | RAM | Hard Drive | Price / Month |
| RTX 4090 | 4 x NVIDIA GeForce RTX 4090 | 96GB (4 x 24GB) | FP32 TFLOPS: 82.6 AI TOPS: 1,321 GPU Memory Bandwidth: 1,008GB/s | 16 Cores 3.0GHz | AMD EPYC™ 9124 | 256GB | 2 x 7.6TB NVME/SSD | MYR 9,499+ |
| RTX 5090 | 4 x NVIDIA GeForce RTX 5090 | 128GB (4 x 32GB) | FP32 TFLOPS: 104.8 AI TOPS: 3,352 GPU Memory Bandwidth: 1,792GB/s | 16 Cores 3.0GHz | AMD EPYC™ 9124 | 256GB | 2 x 7.6TB NVME/SSD | Get Quote |
Notes:
• One-time setup charge: MYR 1,500+.
• +: Subject to 8% SST. Prices are provided as a guide and may vary due to changes in foreign exchange rates.
Related Services
Enhance your GPU experience with IP ServerOne’s solutions, ensuring seamless performance and peace of mind for your AI journey.
NovaGPU
On-demand access to affordable and secure GPUaaS.
- Affordable, dedicated GPU on demand
- Accelerate your AI-driven projects and applications
- Fine-tune models, perform real-time inference, and run simulations on data-sovereign GPUs
Managed Private Cloud
Dedicated and Customized Cloud Environment.
- Heightened security by having full control over your server.
- Customized setup for every need.
- On-prem or legacy system to the cloud.
Colocation
A Safe Space for Your Servers and IT Equipment.
- Neutral-carrier. Tier III data center in CJ1 Malaysia.
- 24x7 NOC support assistance.
- Compliant with ISO27001, ISO27017, PCI-DSS, SOC 2 Type II.
Acorn Recovery as a Service
Restore Your IT Infrastructure within Minutes.
- Managed backup and disaster recovery solution.
- Simplified your ransomware recovery.
- Compliant with ISO27001, ISO27017, BNM RMiT, SOC 2 Type II.
Use Cases for GPU Servers
Common deployment scenarios for our GPU servers.
TECHNOLOGY & AI
AI Model Training & Fine-Tuning
Train and fine-tune large language models (LLMs), computer vision models, and machine learning workloads using dedicated GPU infrastructure.
Dedicated GPU servers provide full access to NVIDIA GPU resources without virtualization overhead, enabling faster model training, larger batch sizes, and more efficient processing of large datasets. This helps AI teams accelerate development cycles while maintaining complete control over their AI environment.
ENTERPRISE AI
Private AI & RAG Applications
Deploy private AI assistants, Retrieval-Augmented Generation (RAG) applications, knowledge bases, and enterprise AI platforms using dedicated GPU infrastructure.
GPU servers provide a dedicated environment for hosting AI models and inference workloads while keeping business data within your controlled infrastructure. This enables organisations to build private AI applications with greater control over performance, security, and data residency.
MEDIA & CREATIVE
Video Rendering & 3D Visualization
Render 3D animations, visual effects, architectural designs, product visualisations, and high-resolution video projects faster with GPU acceleration.
Dedicated GPU servers significantly reduce rendering times for compute-intensive creative workloads. Full access to GPU resources enables creative teams to process complex scenes, larger files, and higher resolutions more. efficiently
RESEARCH & HPC
Scientific Computing & Simulations
Run simulations, financial modelling, engineering calculations, scientific research, and other high-performance computing (HPC) workloads that require substantial compute resources.
GPU servers deliver sustained compute performance for long-running workloads and large-scale calculations. Dedicated resources ensure predictable performance for simulations and research projects that demand consistent processing power.
NovaGPU vs GPU Server: Which GPU Solution Should You Choose?
NovaGPU is a GPU as a Service (GPUaaS) platform for flexible, on-demand GPU computing, while GPU Server provides dedicated bare-metal GPU infrastructure for production AI, HPC, and long-running, compute-intensive workloads.
| Comparison | NovaGPU (GPUaaS) | GPU Server |
|---|---|---|
| Best For | AI development, testing, experimentation, and short-term GPU workloads | Production AI, HPC, large-scale training, and long-running workloads |
| Infrastructure | Dedicated GPU resources delivered on-demand | Dedicated bare metal GPU server |
| Deployment Speed | Fast provisioning with quick access to GPU resources | Dedicated server provisioning and hardware setup |
| Pricing Model | Hourly or subscription-based pricing | Monthly or annually server subscription |
| Control & Performance | Managed environment with cloud flexibility and dedicated GPU resources | Maximum control with dedicated hardware access and no virtualization overhead |
| Choose This If | You need flexible, on-demand GPU compute for AI development, testing, experimentation, or short-term workloads | You need dedicated bare metal GPU infrastructure for production AI, HPC, large-scale training, or long-running workloads |
| Comparison | NovaGPU (GPU as a Service) | GPU Server |
|---|---|---|
| Solution Type | GPU as a Service (GPUaaS) | Bare Metal GPU Server |
| Infrastructure Model | Cloud-based GPU resources delivered on demand | Physical dedicated GPU server hosted in a data center |
| GPU Access | Dedicated GPU resources without sharing | Full access to dedicated physical GPU hardware |
| Scalability | Scale GPU resources based on project requirements | Scale by adding additional dedicated server resources |
| Hardware Ownership | No hardware purchase required | No hardware purchase required; dedicated physical server is allocated to you |
| Infrastructure Control | Managed GPU environment with cloud flexibility | Greater control over the dedicated server environment and hardware resources |
| Performance | Dedicated GPU resources with cloud-based flexibility | Dedicated hardware with no virtualization overhead |
| Security & Isolation | Dedicated GPU resources within a managed cloud environment | Single-tenant dedicated infrastructure with physical hardware isolation |
| Management | Managed by IP ServerOne; customers focus on applications and GPU workloads | Hardware infrastructure managed by IP ServerOne; customers have greater control over the software environment |
| Backup & Disaster Recovery | Cloud backup and availability options can be configured based on requirements | Backup and disaster recovery options can be customized based on requirements |
| AI/ML Development | Suitable for AI development, experimentation, training, fine-tuning, and inference | Suitable for intensive AI development, training, fine-tuning, and production workloads |
| Large Model Training | Suitable depending on GPU configuration and workload requirements | Suitable for sustained large-scale model training workloads |
| LLM Development | Suitable for LLM testing, fine-tuning, and deployment | Suitable for production LLM infrastructure and sustained inference workloads |
| Machine Learning Experiments | Well suited for flexible and short-term experiments | Suitable for ongoing and resource-intensive ML workloads |
| Rendering & Graphics | Suitable for flexible GPU rendering and graphics workloads | Suitable for continuous rendering, 3D modelling, visualization, and graphics workloads |
| High-Performance Computing (HPC) | Suitable for GPU-accelerated HPC workloads depending on configuration | Suitable for sustained HPC, simulations, scientific computing, and large-scale processing |
| Technical Expertise | Lower infrastructure management requirements | Greater control requires more responsibility for the server software environment |
| Ideal Customer | Developers, researchers, startups, SMEs, and teams that need flexible GPU compute | Enterprises, AI teams, research organisations, and businesses requiring dedicated GPU capacity and infrastructure control |
| Comparison | NovaGPU (GPU as a Service) | GPU Server |
|---|---|---|
| Solution Type | GPU as a Service (GPUaaS) | Bare Metal GPU Server |
| Infrastructure Model | Cloud-based GPU resources delivered on-demand | Physical dedicated GPU server hosted in a data centre |
| Best For | AI developers, researchers, startups, SMEs, R&D projects, short-term AI workloads | Enterprises, production AI systems, large-scale workloads, HPC, long-running projects |
| GPU Access | Dedicated GPU resources without sharing | Full dedicated physical GPU hardware |
| Deployment Speed | Fast deployment — provision GPU resources when needed | Requires server provisioning and hardware setup |
| Pricing Model | Flexible hourly or subscription-based pricing | Monthly subscription-based server rental |
| Starting Price | NVIDIA RTX 3090 GPU starts from MYR 1.82/hour | NVIDIA RTX 3090 GPU Server starts from MYR 1,499+/month |
| Hardware Ownership | No hardware purchase required | No purchase required, but dedicated physical server allocated |
| Scalability | Easily scale GPU resources based on project requirements | Scaling requires additional server resources |
| Management | Fully managed by IP ServerOne — users focus on applications and AI workloads | Hardware setup managed by IP ServerOne; customers may manage software or choose managed services |
| Infrastructure Control | Less infrastructure control, optimized for flexibility | Maximum control over server environment and hardware resources |
| Performance Consistency | Dedicated GPU allocation with cloud flexibility | Maximum performance with no virtualization overhead |
| Security Model | Managed GPU environment with dedicated resources and cloud security features | Single-tenant dedicated infrastructure with enhanced hardware isolation |
| Backup & Availability | Includes managed cloud features such as snapshots and high availability options | Backup and DR options can be customized based on requirements |
| Recommended Workloads | AI model training, fine-tuning, inference, experimentation, AI development | Production AI deployment, HPC simulation, large-scale data processing |
| AI/ML Development | Excellent for flexible AI development | Excellent for intensive AI workloads |
| Large Model Training | Suitable depending on GPU configuration | Better for sustained large-scale training workloads |
| LLM Development | Ideal for testing, fine-tuning, and deployment | Ideal for production LLM infrastructure |
| Machine Learning Experiments | Recommended | Possible but may be costlier for temporary projects |
| Rendering & Graphics | Suitable for flexible GPU access | Better for continuous rendering workloads |
| Technical Expertise Required | Lower — managed service | Higher — requires more infrastructure management |
| Ideal Customer | Teams that need GPU power without infrastructure complexity | Organizations requiring dedicated compute capacity and maximum control |
Frequently Asked Questions
GPU servers are high-performance computing systems designed to accelerate processing tasks by using Graphics Processing Units (GPUs) rather than just Central Processing Units (CPUs). These servers are optimized for parallel computing tasks, such as AI/ML, data processing, scientific simulations, gaming, and more, making them ideal for handling demanding workloads.
GPUs are specialized hardware designed to handle multiple calculations simultaneously, which is why they excel at tasks that require parallel processing, such as AI/ML training, video rendering, and simulations. Unlike CPUs, which handle sequential tasks, GPUs can process large chunks of data at once, significantly speeding up tasks like training machine learning models or rendering high-resolution graphics.
GPUs (Graphics Processing Units) were originally designed for rendering graphics but are now essential for AI, data processing, and more. Unlike CPUs, GPUs can process multiple tasks simultaneously, making them ideal for demanding workloads. Common uses of GPUs include:
- AI & Machine Learning: Accelerates AI model training and inference for applications like chatbots, image recognition, and self-driving technology.
- Gaming & Graphics: Powers high-quality visuals in video games, movies, and 3D design for realistic rendering.
- Data Processing: Handles large datasets for research, simulations, and business analytics.
- Cryptocurrency Mining: Solves complex algorithms to validate blockchain transactions.
- Creative Work: Speeds up video editing, 3D modeling, and rendering for professionals.
- Everyday Performance: Enhances app responsiveness and display quality in laptops and mobile devices.
A bare metal GPU is a physical GPU installed in a dedicated server, giving you direct access to dedicated hardware without virtualization overhead. It provides greater control over the server environment and is well suited for production AI, large-scale model training, high-performance computing (HPC), rendering, simulations, and other long-running workloads.
GPU as a Service (GPUaaS) provides dedicated GPU resources through a managed cloud environment. It offers greater flexibility for AI development, testing, experimentation, fine-tuning, inference, and short-term workloads, with hourly or subscription-based pricing.
At IP ServerOne, GPU Server provides dedicated bare metal GPU infrastructure, while NovaGPU provides dedicated, non-shared NVIDIA GPUs on-demand without requiring you to purchase physical hardware.
There are a few types of GPU server deployments, each suited to different needs:
- Bare-Metal GPU servers: Physical servers with dedicated GPUs for tasks like AI/ML training, data processing, and gaming. They provide the best performance for heavy workloads.
- Cloud-based GPU servers: On-demand GPU resources that you can scale as needed, without buying hardware. Ideal for businesses seeking flexible, cost-effective GPU solutions.
- Hybrid GPU servers: A mix of bare-metal and cloud-based resources. This setup gives you the flexibility of the cloud with the performance of physical servers, ideal for businesses that need both scalability and high power for tasks like AI/ML and big data.
Bare metal GPUs deliver dedicated, high-performance computing power without virtualization overhead, making them ideal for AI and intensive workloads. Here’s why they stand out:
- Maximum Performance: Full access to the GPU’s power without shared resources, ensuring faster computations and lower latency.
- Stability & Reliability: No virtualization means predictable performance, making them perfect for AI training, deep learning, and scientific simulations.
- Optimized for AI & ML: Handles complex models, large datasets, and intensive computations more efficiently than virtualized alternatives.
- Flexible & Scalable: Customizable to meet specific AI needs, making them a great choice for businesses with demanding workloads.
- Cost-Effective for Heavy Workloads: Eliminates resource-sharing inefficiencies, providing better value for sustained, high-intensity computing tasks.
Choosing the right GPU server depends on your workload, performance requirements, GPU memory needs, and how much infrastructure control you require. Consider the following factors:
- Define your workload: Identify whether you need the GPU for AI model training, fine-tuning, inference, LLM workloads, scientific simulations, rendering, visualization, or other compute-intensive applications.
- Consider GPU memory (VRAM): Larger models and datasets typically require more GPU memory. Choose a GPU with enough VRAM for your model and workload requirements.
- Evaluate performance requirements: Consider factors such as compute performance, throughput, latency, batch size, and the amount of data you need to process.
- Consider your infrastructure requirements: Bare metal GPU servers provide dedicated hardware, direct hardware access, and greater control over the server environment.
- Plan for future workloads: Consider whether your GPU requirements may increase as your models, datasets, users, or applications grow.
- Consider your budget: Compare the GPU performance and memory you need against your expected workload and usage duration.
If you need flexible, on-demand GPU compute without committing to a dedicated physical server, NovaGPU may be a better fit for development, testing, experimentation, and short-term workloads.
Yes. GPUs are widely used for AI and machine learning (ML) because their parallel processing capabilities can accelerate workloads such as model training, fine-tuning, inference, deep learning, and large-scale data processing.
When choosing a GPU for AI, consider:
- AI workload: Determine whether you need the GPU for model training, fine-tuning, inference, LLM development, computer vision, or other AI workloads.
- GPU memory (VRAM): Larger AI models and datasets generally require more GPU memory. GPUs with higher VRAM can support larger models and workloads.
- Compute performance: GPU architecture, CUDA cores, Tensor Cores, memory bandwidth, and other hardware specifications can affect AI performance.
- Workload duration: For long-running training or production workloads, dedicated bare metal GPU infrastructure provides consistent access to dedicated hardware.
- Budget and flexibility: For flexible or short-term workloads, GPUaaS such as NovaGPU provides on-demand access to dedicated GPUs without requiring a physical server purchase.
IP ServerOne offers GPU options ranging from the RTX 3090 and RTX 4090 to RTX 5090, RTX 6000 Ada, RTX PRO 6000 Blackwell, and H200 NVL, depending on your workload and performance requirements.
The right GPU for AI/ML depends on your model size, workload, VRAM requirements, performance requirements, and budget. IP ServerOne offers a range of NVIDIA GPUs for different AI, ML, HPC, and compute-intensive workloads.
- RTX 3090: Suitable for AI development, experimentation, model training, inference, and other GPU-accelerated workloads where 24GB of VRAM is sufficient.
- RTX 4090: A high-performance option for AI development, model training, inference, rendering, and other demanding GPU workloads, with 24GB of VRAM.
- RTX 5090: Suitable for demanding AI/ML workloads, model training, fine-tuning, inference, and other compute-intensive applications, with 32GB of VRAM.
- RTX 6000 Ada: A professional GPU with 48GB of VRAM, suitable for enterprise AI, visualization, rendering, and other professional GPU workloads.
- RTX PRO 6000 Blackwell: A professional Blackwell-generation GPU with 96GB of GDDR7 memory, designed for demanding AI, visualization, rendering, and high-performance computing workloads.
- H200 NVL: An enterprise-class NVIDIA GPU designed for large-scale AI and HPC workloads, with high-bandwidth GPU memory suited to demanding model training, inference, and data-intensive applications.
For flexible GPU access without purchasing dedicated physical hardware, you can also use NovaGPU, which provides dedicated, non-shared NVIDIA GPUs through a GPUaaS model.
IP ServerOne offers two GPU infrastructure options for AI, ML, HPC, rendering, and other GPU-accelerated workloads: dedicated bare metal GPU servers and NovaGPU, our GPU as a Service (GPUaaS) platform.
| Feature | GPU Server | NovaGPU (GPUaaS) |
|---|---|---|
| Infrastructure | Dedicated physical GPU server | Dedicated GPU resources delivered through a managed cloud environment |
| GPU Access | Full access to dedicated physical GPU hardware | Dedicated, non-shared NVIDIA GPU resources |
| Pricing | Monthly or annual server subscription | Hourly or subscription-based |
| Deployment | Dedicated server provisioning and hardware setup | Fast provisioning with on-demand GPU access |
| Management | IP ServerOne manages the underlying hardware infrastructure; customers can manage their software environment or choose a managed service | Managed GPU environment by IP ServerOne; customers focus on their applications and workloads |
| Control & Performance | Greater infrastructure control with dedicated hardware and no virtualization overhead | Cloud flexibility with dedicated GPU resources |
| Best For | Production AI, HPC, large-scale training, and long-running workloads | AI development, testing, experimentation, and short-term or flexible GPU workloads |
Choose GPU Server when you need dedicated bare metal infrastructure, greater control, and consistent access to physical GPU hardware for production or long-running workloads.
Choose NovaGPU when you need flexible, on-demand access to dedicated GPUs for development, testing, experimentation, training, inference, or workloads that may change over time.